摘要
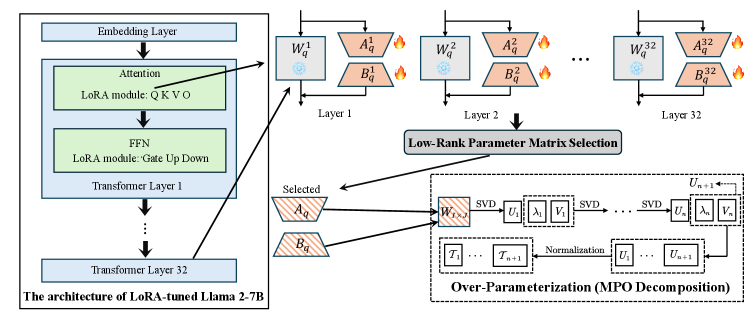
In this work, we introduce LoRA-Over, a framework that enriches the optimization landscape of low-rank adapters during training and folds the extra capacity back into a standard low-rank structure at inference. Across language understanding, dialogue, arithmetic reasoning, and code generation benchmarks, LoRA-Over consistently outperforms vanilla LoRA while keeping the inference cost identical.