Publication

Small Pre-trained Language Models Can be Fine-tuned as Large Models via Over-Parameterization

返回学术发表
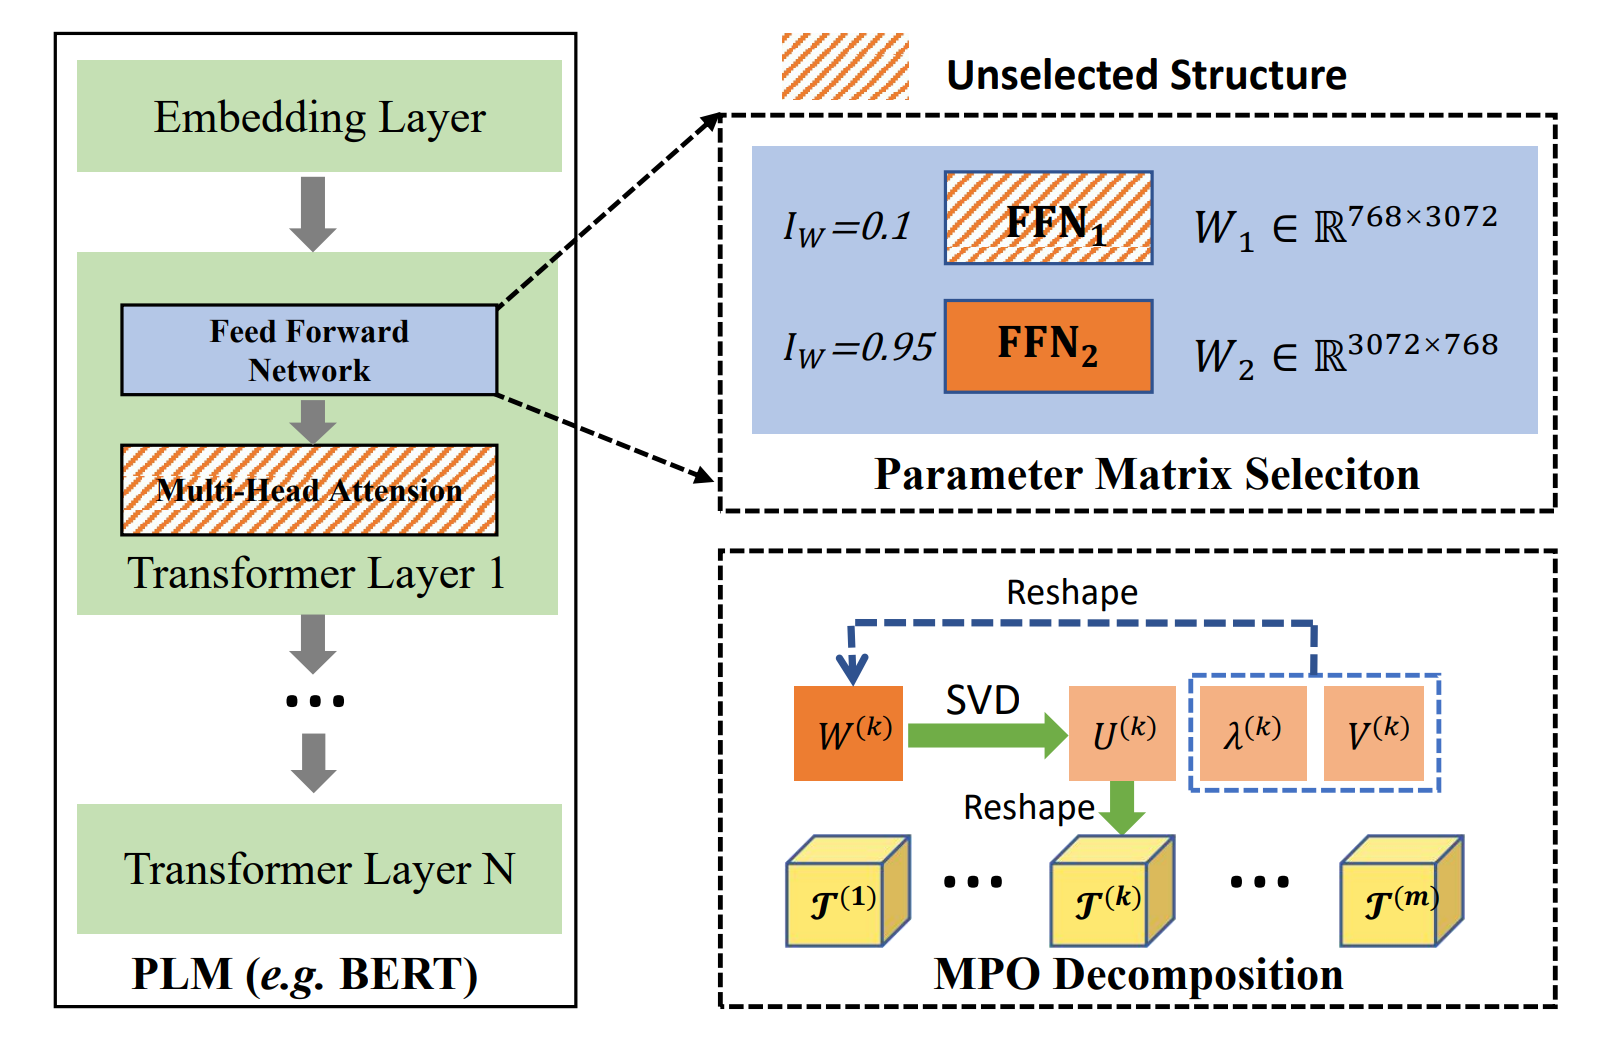
Small Pre-trained Language Models Can be Fine-tuned as Large Models via Over-Parameterization 论文配图

Ze-Feng Gao, Kun Zhou,Peiyu Liu, Wayne Xin Zhao#, Ji-Rong Wen

Annual Meeting of the Association for Computational Linguistics (ACL2023), Oral (Nominated for Best Paper Reward), 2023

摘要

In this paper, we focus on just scaling up the parameters of PLMs during fine-tuning, to benefit from the over-parameterization but not increasing the inference latency. Extensive experiments have demonstrated that our approach can significantly boost the fine-tuning performance of small PLMs and even help small PLMs outperform 3x parameterized larger ones.