摘要
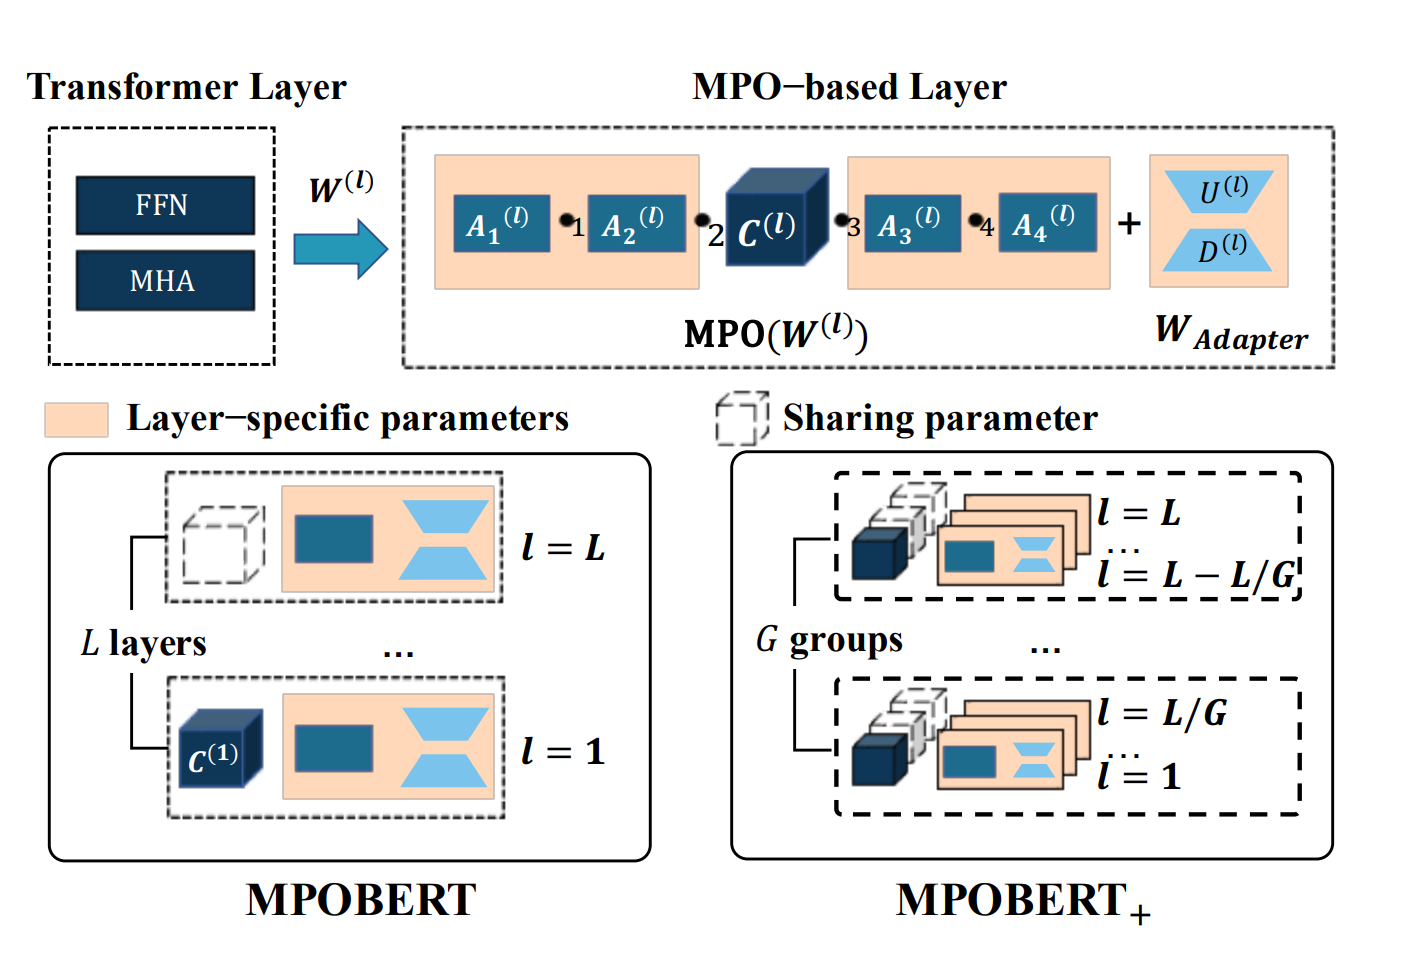
In this paper, we propose a parameter-efficient pre-training approach that utilizes matrix decomposition and parameter-sharing strategies to scale PLMs. Extensive experiments have demonstrated the effectiveness of our proposed model in reducing the model size and achieving highly competitive performance (i.e. with fewer parameters than BERT-base, we successfully scale the model depth by a factor of 4x and even achieve 0.1 points higher than BERT-large for GLUE score).