摘要
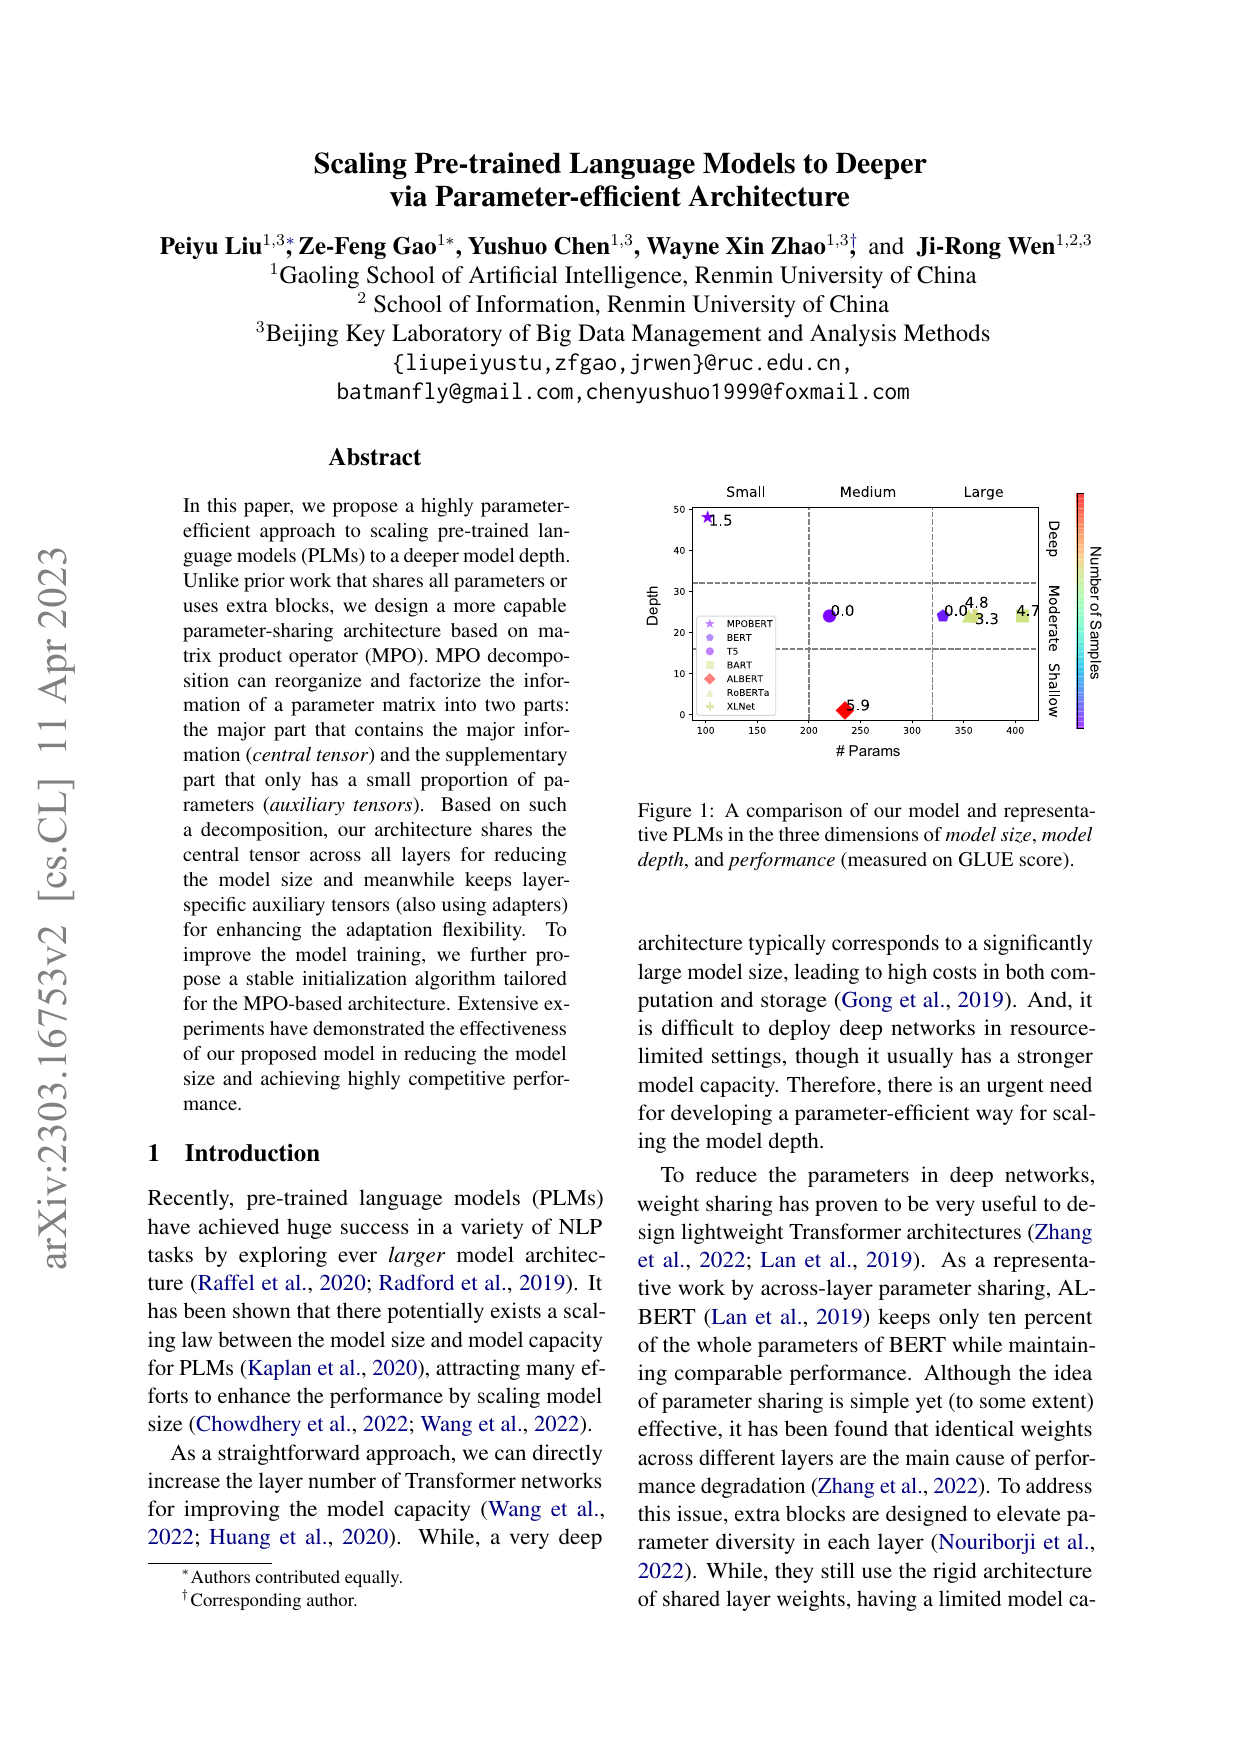
In this paper, we propose a highly parameter-efficient approach to scaling pre-trained language models (PLMs) to a deeper model depth based on matrix product operator (MPO) decomposition, which shares the central tensor across all layers to reduce model size while keeping layer-specific auxiliary tensors and adapters for flexible adaptation.