Publication

Parameter-Efficient Mixture-of-Experts Architecture for Pre-trained Language Models

返回学术发表
Parameter-Efficient Mixture-of-Experts Architecture for Pre-trained Language Models 论文配图

Ze-Feng Gao*, Peiyu Liu*, Wayne Xin Zhao#, Zhong-Yi Lu, Ji-Rong Wen

International Conference on Computational Linguistic (COLING2022), Oral Presentation, 2022

摘要

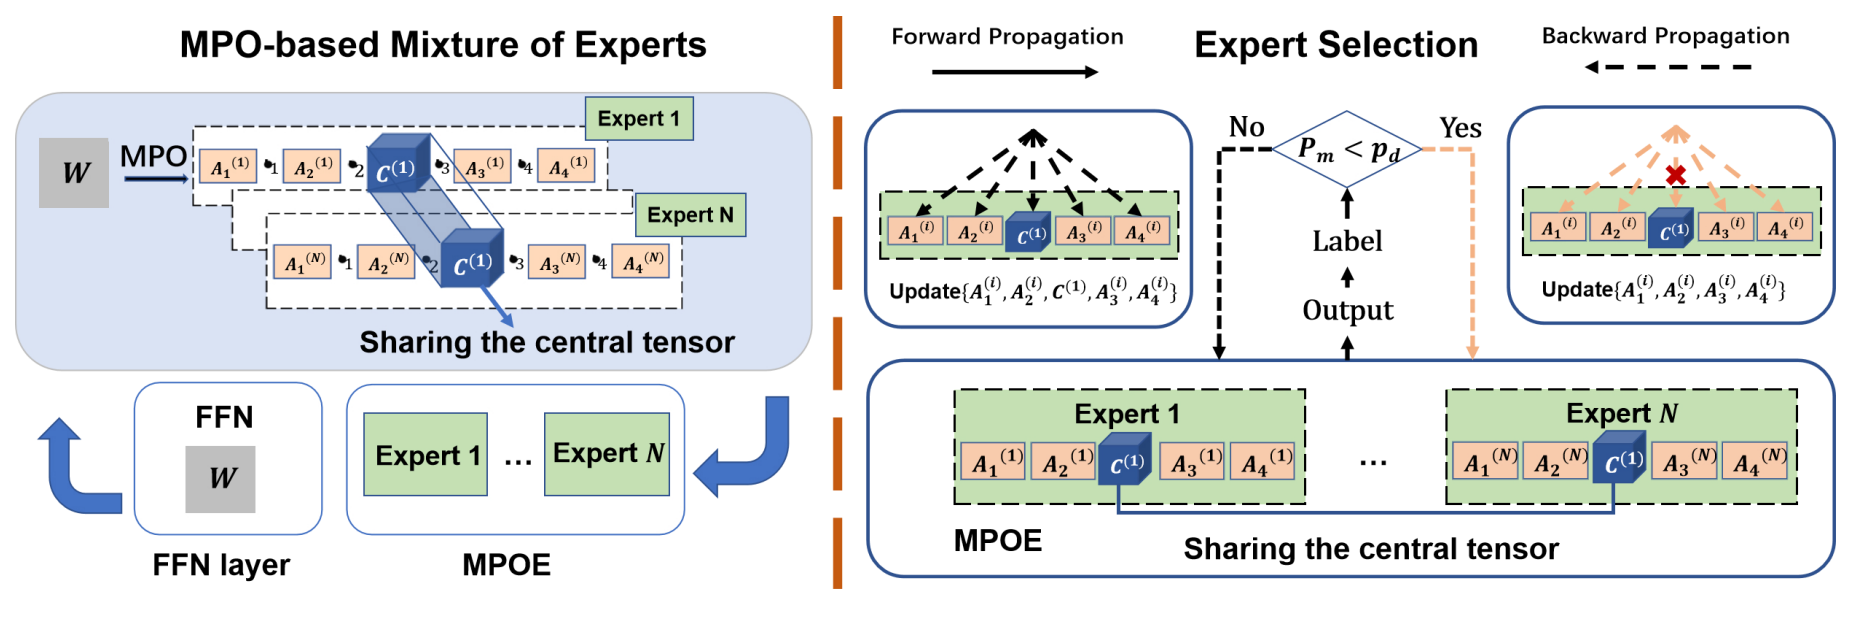
In this paper, we can reduce the parameters of the original MoE architecture by sharing a global central tensor across experts and keeping expert-specific auxiliary tensors. We also design the gradient mask strategy for the tensor structure of MPO to alleviate the overfitting problem.